The Field Report
Why an assistant names your competitor and not you
It is uncomfortable to read a confident answer that recommends your competitor. Before concluding anything, separate what the providers document from what anyone is guessing.
- Author
- Amit GovilFounder and CEO, XONIK
- Published
- October 22, 2026
- Reading time
- 9 min read
In this piece
Voice and options
Read aloud by the voice on your device. Nothing is sent to us.
In brief
An assistant can name only a firm it can verify from the pages it reads. When two firms are equally eligible, the differences we look for are a page that answers the buyer's question in its opening lines, one name and description used everywhere, and independent sources that agree. The providers document eligibility, not selection.
Key findings
Both firms usually clear the documented conditions, and clearing them does not oblige Google to crawl, index or serve the page.
None of these vendors explains how one eligible page is preferred to another, so the piece asks only what an assistant could check, by reading, about each firm.
An assistant works with passages, so a page helps only if it holds text that answers the question as asked.
Google builds snippets from the part of a page that best relates to a specific search, and OpenAI lists opening a page and finding text inside it as separate actions.
A firm with one name and one description everywhere is easier to identify than a firm with variants.
A system reading across the web must decide that the name on one page is the firm on another. Google describes the problem on its Organization structured data page, and says its AI features need no special markup.
Agreement from outside the firm is the kind of evidence a vendor itself treats as relevant to a source.
Google's content guidance asks whether someone researching a site would find it well trusted. That concerns its ranking systems, not the names in an answer, and these checks are our reading, not a documented formula.
The passage can change this quarter, identity takes longer, and corroboration cannot be done alone.
Look first at access, then at the opening of the page, then at how consistently the firm is described. A firm that tries to manufacture mentions is working on the wrong problem.
What can an assistant check about a firm by reading?
Three things, as we read the documents. The first is the passage. Google's guide to snippets says they are created mainly from page content, chosen to preview the part that best relates to a user's specific search, so different searches produce different snippets. OpenAI's search tool lists opening a page and finding text inside it as separate actions. Both describe a pipeline that works at the level of passages. A page helps if it holds a stretch of text that answers the question as asked, not merely if the page is about the right subject.
The second is identity. Google's Organization structured data page deals with the problem of telling organizations apart: it says some properties are used behind the scenes to distinguish one organization from another, and a sameAs property can point to the firm's profile pages elsewhere. Google's AI features page says no special markup is needed, so read this as the vendor describing a problem, not prescribing a fix. A system that reads pages from across the web must decide that the name on one is the firm on another. A firm with one name and one sentence of description everywhere makes that decision easy. A firm with variants makes it uncertain.
The third is corroboration. Google's page on helpful, reliable, people-first content asks whether a page shows clear sourcing and background about its author or site, and whether someone researching the site would find it well trusted or widely recognized as an authority on its topic. It concerns Google's ranking systems, not the choice of names in an answer. It does show that agreement from outside the firm is the kind of evidence the vendor itself treats as relevant to a source.
These three are our reading, not a documented formula. No vendor says they decide the outcome or says how they are weighed.
Where would two eligible firms differ?
Exhibit 1 sets the checks side by side for two firms. The firms are constructed for illustration and are not records of any real business. Both pass the documented conditions. Every difference between them is something a system could establish by reading. Read down the rows and note where the firms part: that is where a check stops being a formality and starts deciding which supplier is named. Compare each row with what your own pages publish today.
Exhibit 1
What an assistant can check about two equally eligible firms
| Check | Firm A | Firm B |
|---|---|---|
| Reachable and eligible to be shown | Yes | Yes |
| Opening of the service page | Says what the firm does, for whom and in what order, in the buyer's words | Opens with an outlook and an invitation to get in touch |
| A passage an assistant could lift whole | A paragraph that answers the question and stands alone | The answer is spread across pages or held back for a call |
| The firm's name and description | One name and one sentence of description everywhere | Variant names, and a description that changes from page to page |
| Other sources about the firm | Trade body, publications and clients describe it the same way | Only the firm describes itself |
How can one equally able firm win a question?
Take a retail business asking which firms can connect its store stock system to its online shop. The first firm has a long record of this work. Its page is titled with a service category, opens on a view of where commerce is heading and describes its method in the vocabulary of its brand. It trades under a short name on its site and its full legal name elsewhere. The only outside descriptions of it are directory entries, each written once and never revisited.
The second firm is no better at the work. Its page is titled with the problem, opens with a paragraph that says what it connects to what and for whom, and describes the order in which the work is done. A trade body's member page and a published talk describe it in the same terms. An assistant composing an answer has a sentence to lift from the second firm and checks that other sources agree. For the first it has nothing it can lift and nothing it can confirm.
That is how we would expect it to go, and it is an inference from how firms describe themselves, not an observation of any assistant. It suggests that the firm named is often the one that was easier to describe, which is not always the one that is better at the work.
The firm named is often the one that was easier to describe, which is not always the one that is better at the work.
An inference from how firms describe themselves, not an observation of any assistant.
Which of the three can you change this quarter?
They move at different speeds. The passage is the quickest, because it is your own text: a page can be rewritten in a day and tested the next. Identity takes longer, because it is every place the firm describes itself, which includes the site, social profiles, speaker biographies, directory entries, press boilerplate and the legal name on documents that end up online. One person should hold the approved name and a single approved description, as a style guide holds a brand, and every outside party that asks for a description should be given that text.
Corroboration is the slowest, and the only one that cannot be done alone. A trade body, a publication or a client describes a firm when it has a reason to, and the reason is usually work it can point to. The straightforward route is to do work that is worth describing and to make it easy to describe correctly. A firm that tries to manufacture the mentions is working on the wrong problem, and the documents we read give no basis for thinking it would help.
In what order do you look for the gap?
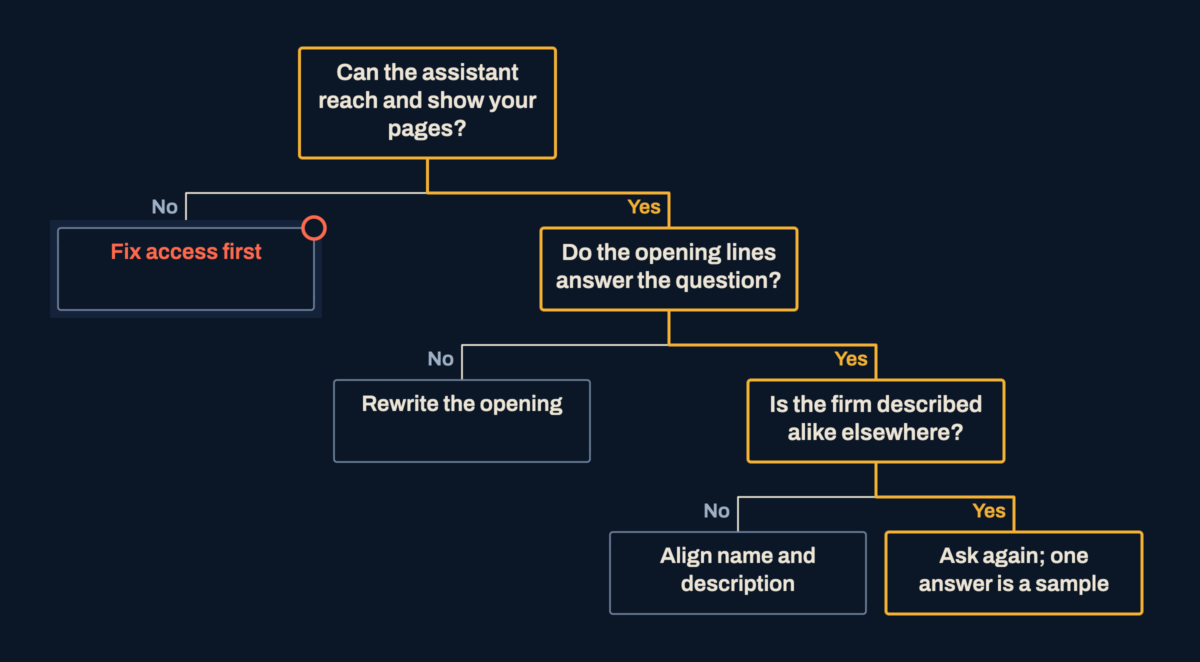
Exhibit 2 gives the order we use. It starts with access because that part is documented and fixable with certainty: a blocked crawler or a page not eligible to be shown ends the inquiry. It moves to the opening of the page, which is cheap to change and easy to test. Only then does it turn to the harder work of making the firm describable in the same way across its own pages and in other people's.
Run each test on more than one day and on more than one assistant before drawing a conclusion. Google's page says its two AI features may differ in the models and techniques behind them, so the links each shows can differ, and the same should be assumed between vendors.
Exhibit 2
The order in which to look for the gap
Text description of this exhibit
The tree starts with a question: can the assistant reach and show your pages? If no, the outcome, marked in red, is to fix access first. If yes, the next question is whether the opening lines answer the question. If no, the outcome is to rewrite the opening. If yes, the last question is whether the firm is described alike elsewhere. If no, the outcome is to align name and description. If yes, the outcome, drawn in blue, is to ask again, because one answer is a sample.
What if the answer did not come from your pages at all?
Then none of the above applies, and nothing the vendors document tells us how often it happens. Anthropic's documentation says Claude answers directly, without searching, when a request draws on stable knowledge, and OpenAI's guide says the model chooses whether to search. An answer given without a search names firms from the model's own recall. OpenAI states that each crawler setting is independent, so a site may allow its search crawler and disallow its training crawler. The pages we read do not say whether training access changes what a model recalls about a firm, and we do not claim it either way.
For the same reason, do not conclude too much from one answer, and do not copy the competitor's page. Two firms with the same description make identity harder for a reader to resolve, not easier.
What does this rest on?
Vendor documents read on 20 October 2026, with the date each shows where there is one, and our experience of how firms describe themselves. No assistant was tested for this piece, and the three checks are inference. Nothing here states how often a firm is named or what any assistant would answer for yours.
- Google Search Central, AI features and your website: what makes a page eligible as a supporting link, and the statement that no special markup is needed
- Google Search Central, Control your snippets in search results: how snippets are created from page content
- Google Search Central, Organization structured data: the properties that tell one organization from another
- Google Search Central, Creating helpful, reliable, people-first content: clear sourcing and whether a site is well trusted
- OpenAI, Overview of OpenAI crawlers: OAI-SearchBot, opted-out sites and independent crawler settings
- OpenAI, Web search guide: the model chooses whether to search, and opening a page and finding text in it are separate actions
- Anthropic, Does Anthropic crawl data from the web: Claude-SearchBot and visibility
- Anthropic, Web search tool: answering directly, without searching, from stable knowledge
- Perplexity, Perplexity crawlers: PerplexityBot, designed to surface and link websites
Use this
Rewrite the first three lines of your most important service page as an answer to one buyer question, then repeat the check.
Related
Does this describe a decision in front of you?
Tell us what is at stake and what has been tried. A senior practitioner replies with a suggested first conversation.