The Field Report
What a pilot gets for free that production has to pay for
The pilot cost next to nothing and it worked. Then the production estimate arrives, and it looks like it belongs to another project. Much of what the pilot ran on never appeared on an invoice.
- Author
- Amit GovilFounder and CEO, XONIK
- Published
- October 22, 2026
- Reading time
- 8 min read
In this piece
Voice and options
Read aloud by the voice on your device. Nothing is sent to us.
In brief
A pilot is cheap because it runs on things nobody pays for: a patient audience, a hand-picked extract, volunteers' time, no audit and nobody on call. Production has to fund each one from a budget sized on the pilot's bill. Listing them with a payer beside each, before the pilot ends, turns a surprise into a plan.
Key findings
The pilot's bill tells you what the model costs and nothing about the work around it.
Every free thing was paid for by someone outside the project, and production sends the bill back to them. A sponsor who sees a good result at a low cost sets the production budget on that basis.
The hand-picked extract turns into a pipeline someone has to build, watch and repair.
Live data arrives with late entries, changed codes and fields typed at the end of a shift, so the model meets a different population from the one it was shown. The pilot never had to ask who answers when a source changes.
Pilot users forgive faults that production users report or abandon.
Early complaints get read as model failure when a good part of it is goodwill running out. What helps is training, a feedback route and an interface that works for people with no stake in its success.
The volunteers and the pager are decisions, not projects.
Production needs reviewers whose time is funded, and a named role with a rota and the authority to switch the system off. If nobody funds the role, the volunteers drift away and the quality goes with them.
Skipped approvals move the go-live date while the build stays put.
Security, privacy, legal and supplier checks are queues held by people outside the project. They can also change the design, for instance by asking for logging the pilot never kept.
Why does running it cost more than the pilot did?
Because the pilot never paid for the conditions that made it work. A pilot is a controlled experiment: a clean sample, willing people, a narrow task, and a safe distance from anything that could go wrong. Someone supplied each of those and didn't charge the project. So the sponsor sees a modest bill and a good result, and sizes production the same way.
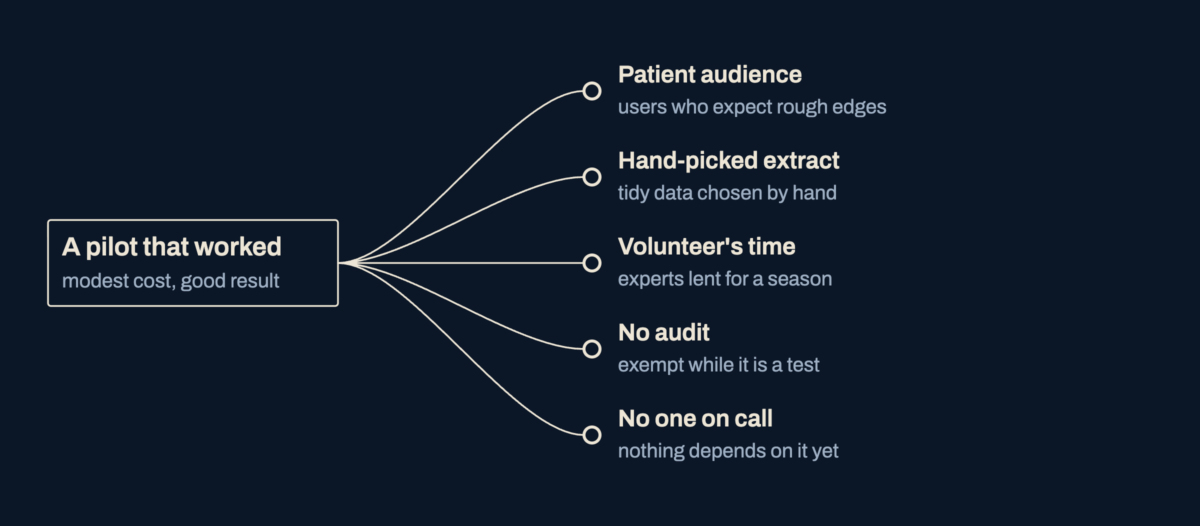
The pilot's spend is a fair guide to what the model costs. It says nothing about the work around the model. The same things come up every time: a patient audience, a hand-picked extract, a volunteer's time, no audit and no one on call. Exhibit 1 lists them. Each is free only because its cost landed on someone outside the project, and in production that someone sends it back.
Exhibit 1
What a working pilot received without paying
Text description of this exhibit
One box on the left reads A pilot that worked, with the note modest cost, good result. Lines lead from it to the right, each ending in a labeled point. The labels, top to bottom: patient audience, users who expect rough edges; hand-picked extract, tidy data chosen by hand; volunteer's time, experts lent for a season; no audit, exempt while it is a test; no one on call, nothing depends on it yet.
The extract and the audience fall due first
Start with the extract. For a pilot, someone pulls a period of records, removes the duplicates, repairs the dates and drops the entries that make no sense. The work is real, it is done once, by hand, by a person whose hours aren't charged to the project. In production the data arrives continuously, with late entries, changed codes and fields typed by tired people at the end of a shift. The model now sees a different population from the one it was shown. The extract becomes a pipeline that somebody has to build, watch and repair, and it brings a question the pilot never asked: who answers when the source changes?
Both a voluntary framework and a regulation treat this gap as something to write down. The NIST AI Risk Management Framework 1.0 asks that limitations of generalizability beyond the conditions under which the technology was developed are documented (MEASURE 2.5). A pilot's conditions are narrow by design, so that limit is exactly what a pilot can't show. Where the EU AI Act applies to a high-risk system, Article 26(4) requires a deployer that controls the input data to ensure it is relevant and sufficiently representative for the system's intended purpose.
The audience is the second thing borrowed. Pilot users volunteered, were told it was an experiment, and sat near the team. They report faults kindly, work around errors and don't count the minutes they spend correcting the output. In production, people are told to use the tool, carry targets of their own and compare it with how they worked before. Each fault is either reported, which loads a support route nobody built, or absorbed in silence, which ends the use. The complaints of the first weeks get read as model failure. A good part of it is goodwill running out, and the cure is training, a feedback route and an interface that works for someone with no stake in its success.
Whose time was the pilot running on?
People are the third. A pilot borrows whoever understands the problem: the senior case handler, the analyst who knows what a bad answer looks like, the clinician who can tell at a glance. They give hours on top of a full job, and their department absorbs the cost without a line in any budget. In production the need stays. Someone has to review samples, decide exceptions and tell the team when the world has changed. Either the role is funded or the volunteers quietly stop, and the quality of the system goes with them. Where the AI Act applies, Article 26(2) requires deployers to assign human oversight to natural persons with the necessary competence, training and authority, as well as the necessary support. That support is the line the volunteer never had.
Then there is the pager nobody carried. While nothing depends on the output, nobody has to answer when it fails at night or at month-end close. In production someone does, which means a named role, a rota, a run book and the authority to switch the system off. Article 26(5) has deployers monitor the operation of a high-risk system and, where they have reason to think its use may present a risk, inform the provider and the market surveillance authority and suspend use. Monitoring and suspension stay words until somebody's working week has room for them.
What did the pilot skip that a live system has to pass?
A pilot is allowed to say it's only a test, and that sentence waives a great deal: the security review, the privacy assessment, legal sign-off, checks on a supplier, accessibility, records retention. None of these is a cost in money first. Each is a queue, held by people who weren't in the project, who keep their own calendars and may say no.
What they ask for can change the design: logging the pilot never kept, access controls it didn't need, a description of the model and its limits, a way to explain an outcome to the person it affects. Where the AI Act applies, Article 26(6) has deployers keep the logs the system generates, to the extent those logs are under their control. Adding that afterward is slower than designing it in. The production plan usually leaves no time for any of it, because it was drawn from a pilot that had none, and the go-live date moves while the build stays the same.
Who pays for each one in production?
The bills don't land on the project, because the project is over. They land on the budgets of the functions that didn't run the pilot. Exhibit 2 sets each free thing against what replaces it, who carries the cost and the first sign it was missed.
Exhibit 2
What replaces each free thing, and who pays
| Free in the pilot | What production needs instead | Who pays | First sign it was missed |
|---|---|---|---|
| Patient audience | Training, a feedback route and support | The business function | Complaints get read as model failure |
| Hand-picked extract | A live data pipeline with monitoring and repair | Technology | Output shifts when a source field changes |
| Volunteer's time | A funded review role, or a share of other roles | The business function | Reviews stop happening |
| No audit | Approvals, logs and a description of the model | Risk and security | The go-live date moves and the build doesn't |
| No one on call | A rota, a run book and authority to pause | Technology and the business | A user finds the outage first |
What does the table tell you?
Look first for a row with no payer. Then look at who the payers are, because it is rarely the sponsor. Technology pays for the pipeline and the rota, the business function for reviewers and training, risk and security for the approvals. Each of them was asked for a view on the pilot. None was asked for a budget.
Which free thing do you miss first?
The table also predicts the order in which things go wrong. The extract goes first, because the data starts behaving differently on the first day and the model's output moves with it. The audience follows, as complaints that sound like criticism of the model. The volunteer and the pager are missed at the first incident, when it isn't clear whose job it is to answer. The audit is missed at the go-live review, when the approvers ask for what the pilot never produced. A team that has read the table can say before launch which of these it will meet first, and who will be in the room.
A row with no payer is an unfunded cost, and unfunded costs get skipped.
How do you size the gap before the pilot ends?
Draw the table for your own pilot before the closing review. For each free thing, write down what it was in this pilot, what will replace it, and the budget holder who has agreed to pay. A row without a signature is the finding. Then ask the sponsor to review the table instead of the demonstration, because the demonstration answers a question the pilot has already settled.
The table orders the work as well. The replacement for the extract has the longest lead time, since it depends on other teams' systems. The approvals are the least predictable, since they depend on other teams' calendars. The volunteer and the pager are decisions, not projects, so they can be taken the day someone is willing to take them.
Sometimes the table shows that production would cost more than the benefit it brings. That is a legitimate result, and it is better reached in an afternoon with a table than after a launch with a bill. A pilot that ends in a reasoned decision not to go ahead has done what a pilot is for.
Sources
We opened both sources on 23 October 2026. Article 26 binds deployers of high-risk systems only, and this piece doesn't say when it applies. The borrowed conditions are patterns from delivery work, not accounts of one engagement.
Use this
Write down what your current pilot is borrowing, and read the list aloud to the people who will be asked to pay for it.
Related
Is a pilot of yours about to move into production?
Send us the pilot's results and the production estimate side by side. Someone senior reads both and replies with what we'd check before you commit.